CCL 2024  ·  Main Conference

Translate-and-Revise: Boosting Large Language Models for Constrained Translation

LLMs skip required terms when they are confident in a more common wording. Translate-and-Revise (TAR) tells the model exactly which constraints it missed and lets it revise.

Pengcheng Huang1,* Yongyu Mu1,* Yuzhang Wu1 Bei Li1 Chunyang Xiao3 Tong Xiao1,2,† Jingbo Zhu1,2
1NLP Lab, School of Computer Science and Engineering, Northeastern University, China 2NiuTrans Research 3JP Morgan
*Equal contribution  ·  †Corresponding author

TL;DRTAR is a training-free prompting method for constrained machine translation. An LLM first translates with the constraints in its prompt; a rule-based check lists the constraints the translation missed; the LLM then revises its own translation given exactly those constraints, and the loop repeats until every constraint is met or a round limit is reached. Across four constrained translation tasks it improves constraint-based translation accuracy by about 15% over standard LLM translation.

Abstract

Imposing constraints on machine translation systems presents a challenging issue because these systems are not trained to make use of constraints in generating adequate, fluent translations. In this paper, we leverage the capabilities of large language models (LLMs) for constrained translation, given that LLMs can easily adapt to this task by taking translation instructions and constraints as prompts. However, LLMs cannot always guarantee the adequacy of translation, and, in some cases, ignore the given constraints. This is in part because LLMs might be overly confident in their predictions, overriding the influence of the constraints. To overcome this overriding behaviour, we propose to add a revision process that encourages LLMs to correct the outputs by prompting them about the constraints that have not yet been met. We evaluate our approach on four constrained translation tasks, encompassing both lexical and structural constraints in multiple constraint domains. Experiments show 15% improvement in constraint-based translation accuracy over standard LLMs and the approach also significantly outperforms neural machine translation (NMT) state-of-the-art methods.

Highlights

15%
higher constraint-based translation accuracy than standard LLM translation
4
tasks: lexical, terminology, named-entity and structured-document constraints
95.9%
constraint completion on WMT21 terminology En→Zh, vs. 88.6% for the best WMT21 submission
0
training: prompting only, and it can also revise the output of NMT systems

At a glance

Task
Constrained machine translation: lexical constraints (dictionary terms, terminology, named entities) and structural constraints (inline XML markup).
Problem
Even strong LLMs given the constraints in the prompt sometimes override them with a more familiar translation, a real-world case of the "memo trap".
Method
Translate with a constraint-aware prompt → detect unmet constraints with rules → prompt the LLM as a reviser with the source, its current translation, all constraints and the unmet ones → iterate.
Models
Main: gpt-3.5-turbo-0613 (temperature 0, one-shot prompts). Also GPT-3 (text-davinci-003), GPT-4 and Qwen-14B-Chat, and as a reviser on top of a WMT21-winning NMT system.
Benchmarks
IATE and Wiktionary (En–De), WMT21 Terminology Translation (En–Zh, En–Ru), Entity Translation Corpus ETC (En–Zh, En–Ru, Zh–En, Ru–En), LXM structured documents (En–Zh/De/Fr/Ru)
Metrics
BLEU, constraint completion rate (CCR), COMET (entities), structure accuracy rate (SAR) and structure match rate (SMR)
Venue
CCL 2024, the 23rd Chinese National Conference on Computational Linguistics (Taiyuan, China), pp. 1059–1074

Why LLMs ignore constraints

Putting constraints in the prompt helps, but it does not guarantee they are followed. Translating an English sentence into Chinese with the constraint COVID-19 → 新型冠状病毒, an open-source LLM still produced the shorter, more common 新冠 more than 80% of the time. Of 20 randomly sampled errors on WMT21 Terminology Translation, 19 were close in meaning to the required term and generated with high confidence, and that confidence barely changed whether or not the constraint was in the prompt. The model is overconfident in the mainstream translation, the pattern McKenzie et al. call the memo trap.

Constraints⟨WHO, 世卫组织⟩; ⟨COVID-19, 新型冠状病毒⟩
SourceOn 11 March 2020, WHO characterized COVID-19 as a pandemic.
Reference2020年3月11日,世卫组织将新型冠状病毒列为大流行病。
Constrained translation2020年3月11日,世卫组织将新冠确定为大流行病。 misses a constraint
+ Revision (TAR)2020年3月11日,世卫组织将新型冠状病毒定性为大流行病。 all constraints met

Case study from the paper: the reviser is told that "COVID-19 should be translated as 新型冠状病毒" and fixes it.

Method: translate, then revise

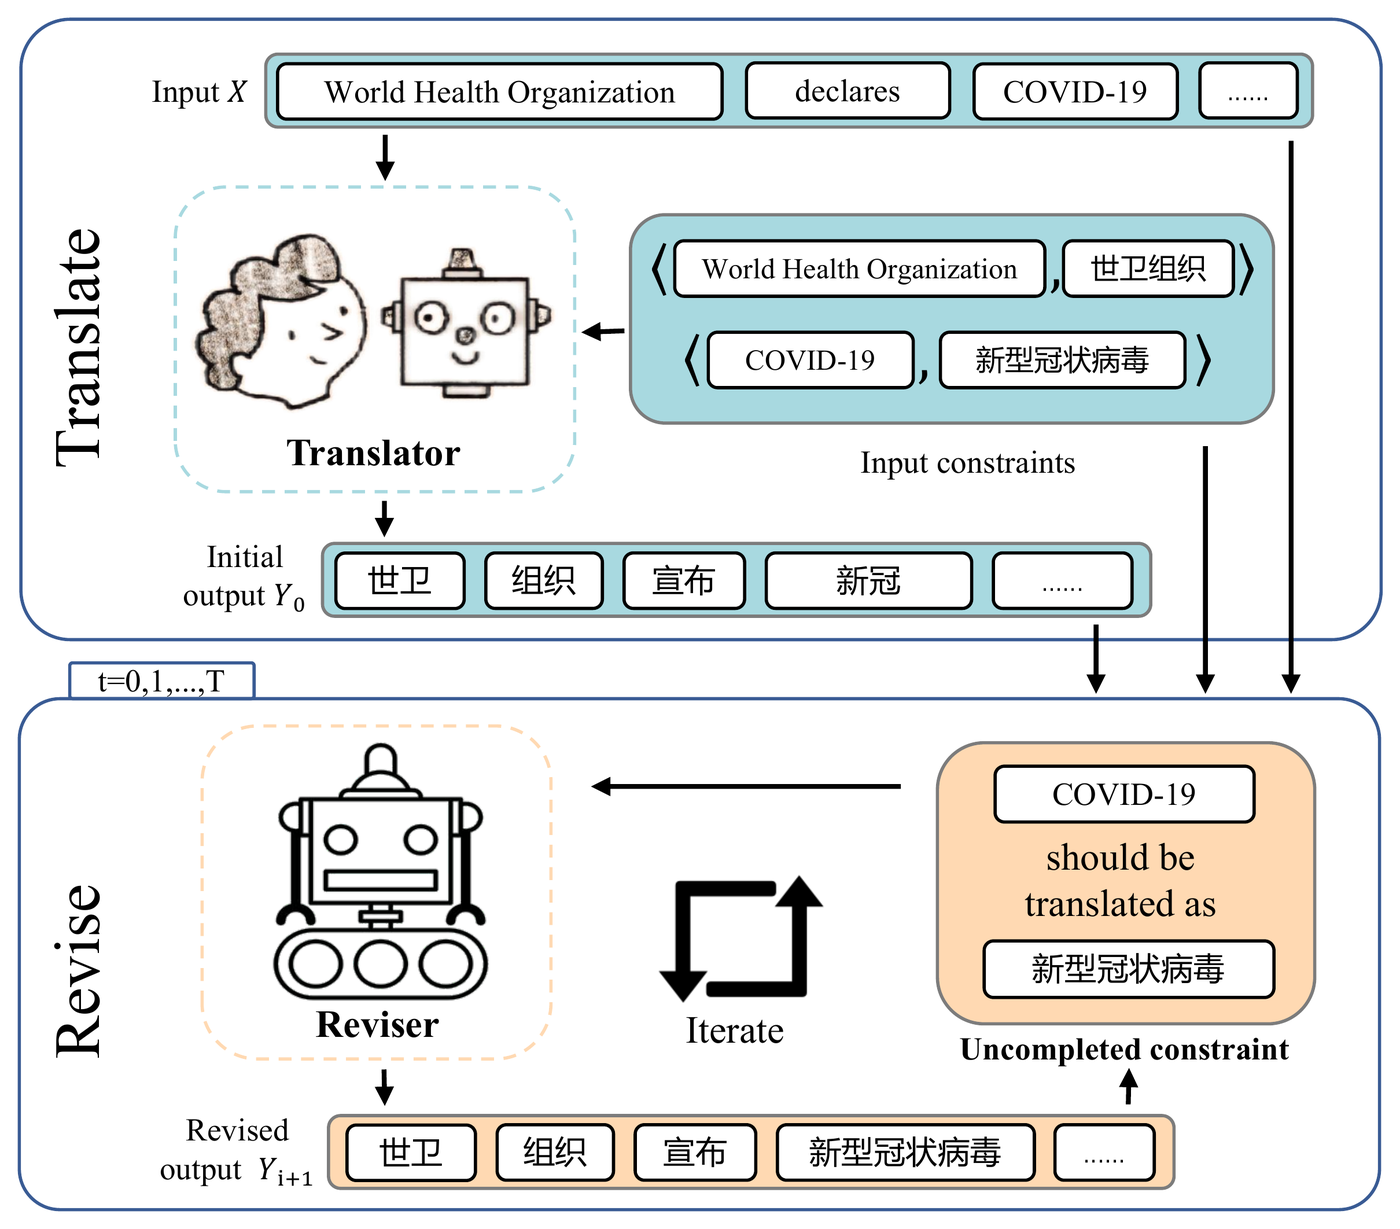
TAR pipeline: a translator produces an initial translation with constraints; uncompleted constraints are detected and a reviser iteratively revises the translation until COVID-19 is translated as 新型冠状病毒.
The Translate stage produces $Y_0$ (here "COVID-19" becomes 新冠). The Revise stage receives the uncompleted constraint and iteratively turns $Y_i$ into $Y_{i+1}$ until the constraint is met.
Stage 1

Translate with a constraint-aware prompt

Given source sentence $X$ and bilingual constraints $\langle S,T\rangle=\{\langle s_1,t_1\rangle,\dots,\langle s_k,t_k\rangle\}$, the LLM must produce $Y=\mathrm{Trans}(f(X,\langle S,T\rangle))$ with every target term $t_i$ in $Y$. A natural-language instruction turns the LLM into a constraint-aware translator:

Translate prompt

Translate the sentence from [src-lang] to [tgt-lang], ensuring the provided constraints are reflected in the translation.
The constraints are given in no specific order. Only provide the translation result.
Sentence: X
Constraints: ⟨S,T⟩
Output:
Stage 2

Revise with the constraints that were missed

A rule-based checker (the same procedure used to compute CCR) finds the uncompleted constraints $\langle S,T\rangle^{un}_i$. The LLM, now acting as a reviser, receives the source, its current translation, all constraints and the uncompleted ones. The loop stops when every constraint is met or a maximum number of rounds is reached:

$$Y_{i+1}=\mathrm{Revise}\big(f(X,\ \langle S,T\rangle,\ \langle S,T\rangle^{un}_{i},\ Y_{i})\big)$$

Revise prompt

Given a sentence in [src-lang], its constraints, and its current translation in [tgt-lang]:
Original [src-lang] sentence: X
Constraints: ⟨S,T⟩
Current translation: Y_flawed
Please provide a revised translation based on the following error message, ensuring that all the constraints are accurately reflected in the translation:
Uncompleted constraints: ⟨S,T⟩_un
Revised translation result:
Four constrained translation tasks

Most earlier work evaluates one or two constrained translation settings. TAR is evaluated on four, covering lexical and structural constraints across news, electronics and other domains, which makes the paper a broad LLM baseline for the area.

TaskDatasetDirection#Sent.#Lines w/ const.#Const.
Lexical constraints
General lexically constrainedIATEEn–De2,000414452
General lexically constrainedWiktionaryEn–De2,000727884
Terminology translationWMT21 TTEn–Ru2,1001,3072,524
Terminology translationWMT21 TTEn–Zh2,1001,1912,229
Entity translationETCEn–Zh / Zh–En19,14412,04035,253
Entity translationETCEn–Ru / Ru–En12,9853,91710,308
Structural constraints
Structured document translationLXMEn–Zh2,000518884
Structured document translationLXMEn–De2,000520942
Structured document translationLXMEn–Ru2,000554993
Structured document translationLXMEn–Fr2,0005751,051

Experimental results

Rows: LLM Trans. uses a conventional translation prompt; LLM Const. Trans. is TAR's Translate stage alone; + Revision is full TAR. All LLM rows use gpt-3.5-turbo-0613. CCR is the constraint completion rate (%).

General lexically constrained translation (En→De)

MethodIATEWiktionary
BLEUCCRBLEUCCR
NMT systems
Transformer25.876.326.076.9
Const. Dec.25.382.025.899.5
Code-switching26.094.526.393.4
Append26.092.826.990.7
RTT27.299.627.898.3
LLM (gpt-3.5-turbo-0613)
LLM Trans.32.085.432.088.7
LLM Const. Trans.32.096.232.197.2
+ Revision (TAR)32.098.932.098.9

Terminology translation (WMT21)

MethodEnglish→ChineseEnglish→Russian
BLEUCCRBLEUCCR
NMT systems
HW-TSC40.788.6--
TermMind-sys240.585.6--
ProMT.soft--31.190.9
TildeMT--28.286.3
Lingua Custodia29.682.828.885.4
LLM (gpt-3.5-turbo-0613)
LLM Trans.36.387.229.785.9
LLM Const. Trans.36.492.630.195.8
+ Revision (TAR)35.995.930.397.5

TAR reaches the highest constraint completion on both directions, above the top WMT21 shared-task systems; HW-TSC keeps a higher BLEU on En→Zh.

Entity translation (ETC)

MethodEnglish→ChineseChinese→English
BLEUCOMETCCRBLEUCOMETCCR
NMT systems
Transformer26.334.857.327.541.559.0
Code-switching25.941.470.527.245.071.1
Placeholder26.442.971.427.547.272.1
Extract & Attend26.848.672.328.050.172.5
LLM (gpt-3.5-turbo-0613)
LLM Trans.39.587.677.227.383.885.3
LLM Const. Trans.40.087.496.628.983.594.2
+ Revision (TAR)40.087.497.628.983.597.3
MethodEnglish→RussianRussian→English
BLEUCOMETCCRBLEUCOMETCCR
NMT systems
Transformer31.852.240.034.654.048.7
Code-switching30.555.250.432.056.750.2
Placeholder31.957.650.334.759.150.7
Extract & Attend32.762.257.335.463.558.4
LLM (gpt-3.5-turbo-0613)
LLM Trans.31.889.964.536.085.876.8
LLM Const. Trans.32.689.888.836.885.896.7
+ Revision (TAR)32.589.889.836.885.897.5

Data-augmentation NMT methods stay at 50–73% CCR on this diverse, multi-year test set, while TAR reaches 89.8–97.6%.

Structured document translation (LXM)

MethodEnglish→ChineseEnglish→German
BLEUSARSMRBLEUSARSMR
NMT systems
Transformer61.299.8599.2552.799.8099.20
Split-Inject57.0100.0099.3050.7100.0099.80
Template61.5100.0099.8053.6100.0099.80
LLM (gpt-3.5-turbo-0613)
LLM Trans.55.199.9598.9549.299.9599.25
LLM Const. Trans.56.4100.0099.5049.299.9599.25
+ Revision (TAR)56.5100.0099.7549.2100.0099.30
MethodEnglish→FrenchEnglish→Russian
BLEUSARSMRBLEUSARSMR
NMT systems
Transformer65.399.5599.3044.999.4598.90
Split-Inject66.1100.00100.0043.1100.0099.85
Template67.3100.00100.0045.8100.0099.80
LLM (gpt-3.5-turbo-0613)
LLM Trans.58.199.9099.3034.499.9099.35
LLM Const. Trans.59.3100.0099.9536.0100.0099.60
+ Revision (TAR)59.3100.0099.9536.0100.0099.75

Bold = best in each column (ties included). Revision raises CCR on every lexical dataset while BLEU stays within ±0.5. On LXM the Translate stage is already at or near 100% structure accuracy, so there is little left for revision to fix.

Analysis

FAQ

What is Translate-and-Revise (TAR)?

TAR is a prompting method for constrained machine translation with large language models, from the CCL 2024 paper by Pengcheng Huang, Yongyu Mu and colleagues at Northeastern University (China). The LLM translates with the constraints in its prompt, then revises its own output after being told which constraints it missed, repeating until all constraints are satisfied.

Why do LLMs ignore translation constraints?

They are overconfident in the translation they saw most often during pre-training. For example, an LLM asked to render "COVID-19" as 新型冠状病毒 kept producing the more common 新冠. The paper links this to the "memo trap" and finds that the model's confidence in such tokens hardly changes when the constraint is added to the prompt.

Does TAR need training or fine-tuning?

No. TAR only changes the prompts and adds a revision loop. The paper applies it to gpt-3.5-turbo, GPT-3 (text-davinci-003), GPT-4 and Qwen-14B-Chat, and also uses an LLM reviser to correct the output of a conventional NMT system.

How does TAR know which constraints are unmet?

With a rule-based check, the same procedure used to compute the constraint completion rate. The paper also tried letting the LLM detect unmet constraints itself; that feedback was less accurate and could degrade the translation.

How does TAR compare with dedicated constrained-translation systems?

Data-augmentation NMT methods are nearly perfect on IATE, Wiktionary and LXM, whose constraints are often seen in training, but reach only 50–73% CCR on the diverse ETC entity test set, where TAR reaches 89.8–97.6%. On WMT21 terminology, TAR exceeds the top shared-task submissions in CCR (95.9 vs. 88.6 En→Zh; 97.5 vs. 90.9 En→Ru), though HW-TSC has higher BLEU on En→Zh.

How many revision rounds are needed?

Most of the gain comes from the first revision; later rounds add progressively less. Varying the revision template across rounds, similar to a prompt ensemble, works better than reusing one template.

中文简介

Translate-and-Revise(TAR):用“翻译—修订”提升大语言模型的约束翻译能力(CCL 2024,第二十三届中国计算语言学大会),作者为东北大学自然语言处理实验室的黄鹏程(Pengcheng Huang)与 Yongyu Mu(共同一作)等,通讯作者为肖桐。

约束翻译要求译文必须使用指定的术语、实体译名或保留 XML 标签结构。把约束写进提示词后,大模型仍会因为对常见译法过度自信而忽略约束,例如要求把 “COVID-19” 译为“新型冠状病毒”,开源模型八成以上的情况仍译成“新冠”。

TAR 无需训练:先用带约束的提示让大模型翻译,再用规则检查哪些约束没有满足,把原文、当前译文、全部约束和未满足的约束一起交给大模型修订,循环直到约束全部满足或达到轮数上限。论文在通用词汇约束(IATE、Wiktionary)、术语翻译(WMT21)、实体翻译(ETC)和结构化文档翻译(LXM)四类任务上评测,约束完成率比普通大模型翻译平均提升约 15%,在 WMT21 术语翻译任务上的约束完成率超过当年的最佳参赛系统;TAR 还可以用来修订传统神经机器翻译系统的输出。

BibTeX

@inproceedings{huang-etal-2024-translate,
    title = "Translate-and-Revise: Boosting Large Language Models for Constrained Translation",
    author = "Huang, Pengcheng and Mu, Yongyu and Wu, Yuzhang and Li, Bei and Xiao, Chunyang and Xiao, Tong and Zhu, Jingbo",
    booktitle = "Proceedings of the 23rd {C}hinese National Conference on Computational Linguistics (Volume 1: Main Conference)",
    month = jul,
    year = "2024",
    address = "Taiyuan, China",
    publisher = "Chinese Information Processing Society of China",
    url = "https://aclanthology.org/2024.ccl-1.82/",
    pages = "1059--1074",
}